
API / CDC
EVENTS / FILES
SENIOR DATA ENGINEER · RALEIGH, NC
I’m Bhanu Vejendla, a Senior Data Engineer with 7+ years of experience turning high-volume data into reliable systems across Azure, AWS and GCP.
A good data platform should be reliable today and understandable six months from now.
I started my data engineering career in India and later continued it in North Carolina, moving through healthcare, financial services, gaming and insurance. Those environments were very different, but they taught me the same lesson: data becomes valuable only when people can trust it.
That is why I care about the work after launch—the quality checks, recovery paths, monitoring, security, performance and cost that keep a platform dependable. I build reusable patterns so the next engineer can understand, operate and extend the system without starting over.
Each role has strengthened a different part of my data engineering experience.
Reusable ingestion patterns and reliable reporting datasets.
90% less infrastructure management time through Terraform automation.
Curated BigQuery datasets and visibility into platform costs.
Batch and streaming pipelines with built-in quality checks.
Grouped by where they fit in the work, from ingestion through production delivery.
Reliable movement from source to platform.
 Kafka
 Airflow
 Azure Data Factory
 APIs & Postman
 Apache NiFi
 AWS Glue
 Cloud Dataflow
Apache Beam
 Java Message Service
Batch and streaming transformations at scale.
 Apache Spark
 Databricks
 Python & PySpark
 dbt
 SQL
 Hadoop
 Apache Storm
Dataproc
Java
Governed storage and analytics-ready models.
 Snowflake
ADLS
Amazon S3
 BigQuery
Delta Lake
 Apache Parquet
PostgreSQL
Azure Blob Storage
Azure Synapse
Azure SQL Warehouse
Amazon Redshift
DynamoDB
 Elasticsearch
SnowSQL
Repeatable infrastructure and production delivery.
Microsoft Azure
AWS
Google Cloud
 Terraform
 Docker
 Kubernetes
 GitHub Actions
 Jenkins
 Git
 Grafana
 Kibana
AWS Lambda
Cloud Monitoring
 Looker Studio
Docker Swarm
Idempotent pipelines · Data contracts · Automated testing · Checkpointing · Backfills · Lineage · Monitoring · Secure access
The tools change by platform. The engineering discipline stays consistent.
Illustrated workflow showing my delivery process.
Volume, latency, ownership and failure modes.
Schemas, quality rules, SLAs and access.
Replayable batch or streaming ingestion.
Tested, incremental and scalable processing.
Governed tables and analytics-ready products.
Monitoring, recovery, performance and cost.
Five projects showing production ownership, practical architecture and reliability—from a live community platform to data engineering systems.
Choose a project to review the problem, engineering decisions and supporting evidence. Each case study links to the live site or source repository.
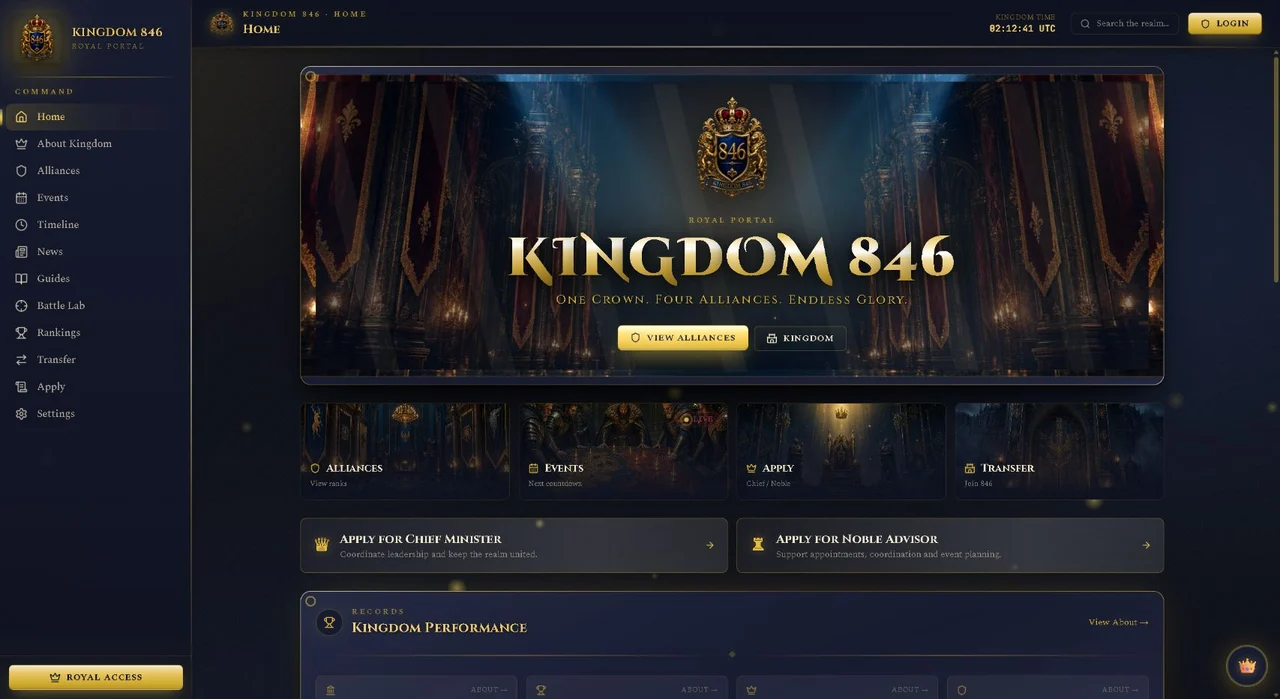
A gaming community needed one dependable place for alliance information, live rosters, applications, rankings, voting and operational updates. I built Kingdom846 as a responsive platform used by real community members.
I separated the React interface from an Express API, persisted operational data in SQLite and enforced role boundaries for administrators, alliance leaders and War Room users. Rate-limited authentication, version-aware updates and a server-side Royal Advisor make the platform practical to operate.
Several authorised War Room users can edit one shared roster. A simple last-write-wins save could erase newer work without warning.
Each client saves the version it started from. The API refuses a stale version with a conflict response instead of accepting an unsafe write.
The interface shows who saved the current version and lets the editor load it or deliberately replace it. The conflict becomes visible and recoverable.
Five short technical stories about failures, trade-offs and safeguards that are difficult to show in a project summary.
Turning a silent last-write-wins risk into a visible, recoverable conflict.
Express · SQLite · Concurrency 02 · WEBLOG STREAMHow a count exposed silent data loss and led to replay-safe Parquet writes.
Kafka · PySpark · Parquet 03 · NYC TAXI LAKEHOUSEMaking monthly loads safe to retry with partition replacement and a durable manifest.
PySpark · Manifests · Backfills 04 · RETAIL WAREHOUSEReprocessing a small trailing window without duplicating yesterday’s orders.
dbt · Incremental SQL · Testing 05 · DATA PLATFORM TERRAFORMEncoding production safety in the configuration and proving it at plan time.
Terraform · AWS · GuardrailsBuilding a team around batch pipelines, streaming systems or cloud data platforms? Share the role, location and the engineering challenges you’re working on.